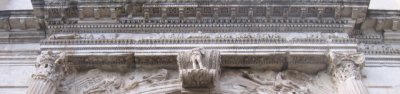
arch detail

arch detail

Friday, September 02, 2011

Crazy C program

I don't know why I love this, but you can actually call main() from inside a C program! Or at least, with GCC 4.4.3 will let you. I wonder if other compilers allow this?

#include 


int main(int argc, char** argv) {
if (argc == 0) {
return 0;
}
else {
printf("%s\n", argv[0]);
main(argc - 1, &(argv[1]));
}
}


Compile it and try:

$ ./a.out a b c d

./a.out
a
b
c
d
Wednesday, November 17, 2010

C++ Iterators: Interesting bug

I've often heard it said that C++ lends itself to surprising and subtle bugs. I recently encountered an interesting (and simple) example myself.

I have a class foo which holds an iterable implemented with the STL (say, in this case, a std::set of ints); say this iterable is called myBar. So we give foo public member functions getBar() and setBar().

class foo {
public:
const std::set getBar() { return myBar; } const;
void setBar(std::set newIntSet) { myBar = newIntSet; };

private:
std::set myBar;
};


At one point, I wanted to iterate over myFoo.myBar, so I used the following:

std::set::const_iterator barIter;
for (barIter = myFoo.getBar().begin();
barIter != myFoo.getBar().end();
barIter++) {
Do work on barIter
}


This periodically produced some really horrible behavior. Do you see why?

It's because we call getBar() once when we start the "for" loop (barIter = myFoo.getBar().begin()) and get one copy of myFoo.myBar. At every successive iteration of the loop, we get another copy of myFoo.myBar, when checking for the termination condition: barIter != myFoo.getBar().end().

Amazingly, this didn't manifest right away with a seg fault or other conspicuous error. This is probably because for all STL iterators that I know of, .end() evaluates to NULL, so we could iterate barIter until it pointed at a 0 in memory, at which point the iteration would stop.

Surprisingly, on my program barIter would usually point at memory which held a copy of myBar. It wasn't until we had a non-trivial program that I found this bug; in fact, this broken program would often pass unit tests!

Overall, this was a boneheaded mistake on my part. Once I put on my C programmer cap and thought about what the compiler was doing, it was easy to see why this was wrong.

Overall, this experience strengthens my belief that one should never do C++ without doing a lot of low-level C programming first, and that C++ classes can hurt as much as they can help.

Saturday, November 06, 2010

Pulseaudio -> JACK2 on Ubuntu 10.04

So, I'm running Ubuntu 10.04 and decided I wanted to run PulseAudio into Jack. Turns out you can do this now! Hurrah!

First, Pulseaudio must be able to write to create a JACK sink. You can add that functionality with:

sudo apt-get install pulseaudio-module-jack


Oddly, this does not automatically enable the module in PulseAudio. So to get it auto-loaded into PulseAudio, I dutifully follow instructions HERE and I do the following:

I edit /etc/pulse/default.pa and change:

### Load audio drivers statically (it is probably better to not load
### these drivers manually, but instead use module-hal-detect --
### see below -- for doing this automatically)
#load-module module-alsa-sink
#load-module module-alsa-source device=hw:1,0
#load-module module-oss device="/dev/dsp" sink_name=output source_name=input
#load-module module-oss-mmap device="/dev/dsp" sink_name=output source_name=input
#load-module module-null-sink
#load-module module-pipe-sink

### Automatically load driver modules depending on the hardware available
.ifexists module-udev-detect.so
load-module module-udev-detect
.else
### Alternatively use the static hardware detection module (for systems that
### lack udev support)
load-module module-detect
.endif


to:

### Load audio drivers statically (it is probably better to not load
### these drivers manually, but instead use module-hal-detect --
### see below -- for doing this automatically)
#load-module module-alsa-sink
#load-module module-alsa-source device=hw:1,0
#load-module module-oss device="/dev/dsp" sink_name=output source_name=input
#load-module module-oss-mmap device="/dev/dsp" sink_name=output source_name=input
#load-module module-null-sink
#load-module module-pipe-sink
load-module module-jack-source
load-module module-jack-sink

### Automatically load driver modules depending on the hardware available
#.ifexists module-udev-detect.so
#load-module module-udev-detect
#.else
### Alternatively use the static hardware detection module (for systems that
### lack udev support)
#load-module module-detect
#.endif


Of course, I also add back up my default.pa and add some comments in there announcing to myself when I changed it, why, and where the backup is. Tutorials should tell you to do that, but they never do, for some reason.

Next, I kill off pulse and restart it, which should force it to load the new modules:

 pulseaudio -k ; pulseaudio 


For some unholy reason Ubuntu is respawning pulseaudio if it is killed, so sometimes the above doesn't work; sometimes inbetween the "pulseaudio -k" to kill and "pulseaudio" to restart, the system reboots pulseaudio. I suck at Gnome and have no idea how to fix this but whatever.

At this point, I make sure JACK is running and use System -> Preferences -> PulseAudio Preferences (that's paprefs, you may need to install it) to make sure the JACK sink is my default output.

I then try opening Movie Player to test. Failure! I get a weird error from Movie Player and my terminal running PulseAudio now says:

W: module-jack-sink.c: JACK error >zombified - calling shutdown handler< 


Then it seg faults. Whoooo!

I do some Googling. It seems that there is a problem with the interface between PulseAudio and JACK but the PulseAudio folks claim that this is now stabilized in newer versions of JACK: "There was some breakage in this area in JACK a while ago. I assume that this problem does not exist anymore. If it does feel free to reopen."

So, it seems that the version of JACK shipping with Ubuntu 10.04 is not compatible with the version of PulseAudio and/or pulseaudio-module-jack. So it's time to install JACK2, the current version of which is (oddly) 1.9.6. You can download the source here.

I download and untar the file:

$ mkdir ~/builds
$ cd ~/builds
$ cp ~/Downloads/jack-1.9.6.tar.bz2
$ bunzip2 jack-1.9.6.tar.bz2
$ tar -xvf jack-1.9.6.tar
$ cd jack-1.9.6


I read the README file and discover I'll need the ALSA and Freebob headers, so:

apt-get install libasound2-dev libfreebob0-dev


Now I have to configure and build. The README instructs me to use ./waf, but they don't really warn me about the options I need on ./waf configure. I used ./waf configure --help and determined that we need --alsa to build with ALSA support and --freebob to configure with Freebob support. Also, since I'm a cautious dude and don't want to hose my system, I also specify --prefix=$HOME and when I install, I use "./waf install" instead of "sudo ./waf install" to get a per-user, locally-installed JACK2 rather than overwrite the old JACK which is installed by Ubuntu.

So in total, do this in the jack source directory you untarred:
 $ ./waf configure --prefix=$HOME --alsa --frebob
(Check that that goes okay.)
$ ./waf build
$ ./waf install


Done! Now you should have jackd in your ~/bin/ and libraries in your ~/lib.

You'll now need to set up your LD_LIBRARY_PATH to use ~/lib/ before the system libraries in /usr/, etc. so that the correct libjack is loaded; you may also wish to modify your PATH variable. For me:

$ echo 'LD_LIBRARY_PATH=$HOME/lib/:$LD_LIBRARY_PATH' >> ~/.bashrc
$ echo 'PATH=$HOME/bin:$PATH >> ~/.bashrc
$ source ~/.bashrc


This will mean that apps you launch from a terminal should now use the new JACK2, but Ubuntu's launch buttons don't seem to pick it up. I'm working on that.

Friday, March 20, 2009

/dev/random and /dev/urandom

This is likely common knowledge, but I hadn't possessed it before. I'd always wondered why sometimes something like
cat /dev/random > randomStuff

would be so oddly-behaved.

It's because /dev/random will block until there is sufficient data floating around in the system (keystrokes, network packets) for the OS to come up with something sufficiently random. /dev/urandom just degrades your random-ness in order to stay speedy. Cool.

Tuesday, March 03, 2009

/bin/false

Consult
man false
someday.

FALSE(1)                         User Commands                        FALSE(1)


NAME

false - do nothing, unsuccessfully


... that is all.

Monday, September 08, 2008

C++ Irritation

In C++ (compiled with g++), the following will use foo's copy constructor:


foo f;
foo g = f;


Whereas I had really imagined it would use the default constructor, followed by the operator= function if present.

In other news, I am working on interesting stuff but haven't spoken about it yet. See CIL, the C Intermediate Language for a really interesting approach to compiler IR: It uses (a subset of) C as an intermediate language for C.

Monday, June 09, 2008

Followup on Ubuntu/SATA issues

I promised to inform the world if I solved my Ubuntu problems using a PCI-SATA adapter and my old SATA disk (My PCI-SATA ubuntu misadventures).

Unfortunately, I haven't. Even using the SATA disk *not* as the boot disk, any significant I/O causes the whole system to freeze - no Ctl-Alt-Backspace or Ctl-Alt-Delete response. So it seems the mundane is true: Ubuntu really doesn't support my hardware.

I've upgraded to 8.04 on my laptop, though, and will soon follow suite on that desktop machine. Maybe I'll be in luck.

Wednesday, June 04, 2008

output of Unix/Linux/*nix time (/usr/bin/time) into a file

I've encountered this problem before:

$ time somecommand arguments 2>&1 >> some_file.txt

real 0m0.001s
user 0m0.001s
sys 0m0.000s


And it drives me crazy. Why doesn't the program 'time' write its output to the, erm, 'normal' stdout or stderr, the ones I'm redirecting? Supposedly, you can use

 time -o outfile.txt somecommand arguments 
(or -a for append) to get the desired effect, but only on GNU time. And inexplicably, this doesn't work on most systems I've used.

Of course, if you Google for anything along the lines of 'time redirect i/o' you'll get a million matches to shell script tutorials saying "this time, we'll use I/O redirection..."

Eventually, I realized that Googling for "/usr/bin/time I/O redirect" got some useful results.

Well, if you're using non-GNU time, and you're using bash or sh (who knows, maybe even csh works this way?), you can do this:

$ ( time command arguments ) 2>> time.out > command.out


Which is a big ol' ugly hack, but it works.


UPDATE:


So the venerable aaron has informed me that I wasn't getting /usr/bin/time, I was getting the bash builtin command 'time' - hence

$env time
/usr/bin/time


and yet the command 'time' does not behave as expected. I should have seen that one coming. The obvious workaround is to explicitly call /usr/bin/time instead of time.

This strikes me as particularly frustrating as bash is a GNU project, and yet it's builtin 'time' does not behave like the 'real' GNU time, but ah well.

Monday, May 26, 2008

Great, doomsaying article on IPv4/v6

Here is a great article about IPv4, why it's dangerous, why it's here to stay, and what we can expect for the future of the Internet. Basically, we shouldn't expect a sane free market for trading around free pools of IPv4 addresses, we can expect hacks upon hacks and most likely all kinds of monetary horrors. Imagine what happens when moveOn.org has to apply for a batch of addresses owned by Halliburton.

Sunday, May 18, 2008

Most useful command-line utility

$your-package-manager install cowsay
$ fortune | cowsay
________________________________________
/ The difference between a Miracle and a \
| Fact is exactly the difference between |
| a mermaid and a seal. |
| |
\ -- Mark Twain /
----------------------------------------
\ ^__^
\ (oo)\_______
(__)\ )\/\
||----w |
|| ||

Wednesday, April 23, 2008

PCI-SATA/Ubuntu misadventures

So, I finally decided it was time to drop the Windows/Cakewalk life for good and install UbuntuStudio (well, Ubuntu, then later upgrade to UbuntuStudio) on my Athlon XP+ recording machine.

I had this brilliant idea to put / onto a SATA disk, both because I had one laying around and because it would be better for recording and pretty much any other media-centric task. Unfortunately, my motherboard does not support SATA!

So for <$40 I got a PCI-SATA adapter (VIA chipset). Happily, my Ubuntu LiveCD detected the attached SATA disk and was more than happy to install on it.

(correction to the above: I had sporadic freezes, but managed several successful installs. However, I do think faulty SATA or PCI-SATA adapter drivers were responsible. running "tail -f /var/log/messages" I was able to see many odd messages; not positive if updated drivers will fix this or it will become a persistent problem.)

Unfortunately, on attempting to boot into the newly-installed environment, I got an ever-so-helpful numeric error from GRUB, in this case, "Error 21". I tried re-running grub-install and editing my /boot/grub/menu.lst on the newly-created system, suspecting that my BIOS might be renumbering my drives when it tried to boot from the MBR of the SATA disk. No dice. At some point I managed to move from "Error 21" in GRUB to a straight "HARD DRIVE BOOT ERROR" from my BIOS.

I heard quite a few suggestions, but really, the Internet has not been much help on this one. I suspected GRUB itself was the problem.

So I tried using SuperGrub, which is basically just GRUB with lots of fancy features and burnable to CD (or copy-able to floppy, or to USB stick, and so on).

Running in SuperGrub, I was able to discover that though grub-install and the grub shell could happily find my SATA disk when running inside of a GNU/Linux LiveCD environment, GRUB itself had no idea. It was totally unable to see the SATA disk. So apparently what happened was that BIOS boots off the MBR, GRUB gets control of the system, and then, well, nothing. GRUB can't find its own files.

So, as a result, I had to do something ugly: I put /boot on a spare IDE disk I had lying around (one which, admittedly, I don't 100% trust, as it had a CRC error once or twice) and put / on the SATA disk. Ubuntu's installer went very nicely from there. Not particularly elegant, but it is effective.

I'm now happily writing you from Ubuntu. It's much faster than my Gentoo machine, but I don't know why; Firefox (even on Windows) was always faster on my Athlon XP+ 3500 than my Gentoo P4 (1.8 GHz), either because of my inability to intelligently manage libraries/drivers on Gentoo, or because the P4 is held back by its weak floating point unit. The SATA certainly doesn't seem to hurt, either; I boot in record time and applications open with wonderful snappiness.

In conclusion: SATA is great, but don't try to rely on it as a boot disk if you're connected via a PCI-SATA card adapter.

Friday, November 09, 2007

Gentoo and Firefox-bin

On my home Gentoo machine, my Firefox experience has been painfully slow lately. I haven't been sure why. So I emerged firefox-bin, the pre-compiled version. It's probably twice as fast - though still sluggish compared to comparable Fedora machines I've been working with. What the heck is Gentoo doing so wrong? Ack.

Portage is the right approach for managing packages. I don't know if I could stand apt. It's a shame that Portage so caught up in the Gentoo community, which is just painfully stupid these days.

Friday, October 26, 2007

Hardware tools for automated rootkit detection

eBay recently reported that surprisingly, a large number of their Linux boxes falling victim to rootkits and joining spam botnets. So Linux is officially a target, which got me thinking...

As far as I can know, the best way to beat a rootkit is to run another, trusted OS and have it examine the disk of the suspect machine, for example checksumming the kernel image and other
system files to make sure they haven't changed.

Unfortunately, this requires a human hand to shut down the machine and boot off of a CD.

It would be nice if, for example, you could configure a cron job to shut down the machine periodically and just leave a CD in the tray, with BIOS configured to boot the CD and do rootkit detection before rebooting from the disk.

Unfortunately, the rootkitted OS could simply refuse to reboot, or even give a reasonable impression of rebooting and scanning itself.

So I've been thinking that it would be more practical for companies like eBay, who have significant resources and wish to avoid becoming botnets, to have a single, very secure
computer (thoroughly protected from the outside world) which would be capable of forceably shutting down other machines, mounting their disks, and doing checksums, over a dedicated and very secure network. If the serverload is already spread out and redundant
for fault-tolerance, this wouldn't really be an inconvenience.

Unfortunately, I'm not sure this is possible - you couldn't buy, off the shelf, a machine with a NIC wired directly to the motherboard with the ability to just power off the whole machine,
without even contacting the OS.

The Trusted Platform Module, or TPM, is actually capable of doing something similar. It can DMA system memory and potentially cut power to the CPU if certain conditions are or are not present. The problem, then, is how to communicate with the TPM without going through the parent OS.

Anybody know a good way? And how hard could it really be for hardware manufacturers to build in the required tools to shut down a system from a remote machine? Do any such hardware manufacturers exist?

Saturday, August 04, 2007

Kororaa Linux

It's been a long few months!

I've been busy lately, hence the lack of updates. I'm back to work at LSST, integrating the Moving Object Pipeline System (which identifies objects in various images of the sky, then identifies common objects in images, then builds a database of their orbits and predicts their motion) into the overall LSST data framework.

Today, I took a break from it all to install Kororaa Linux. Kororaa is a Gentoo fork which has a LiveCD with full AIGLX/XGL environments, allowing all the nifty "wobbly windows" effects and OS X-like expose features. Since I now have an ATI Radeon card, I thought it might be a fun toy. Best of all, the install feature actually gets a whole running Gentoo system installed in under an hour, and pre-configured for super-slick video tricks.

Kororaa uses only open-source drivers, so it is morally correct, but unfortunately, the open-source Radeon drivers proved to be tragically slow. While I thought the lagginess of the system was related to running off a LiveCD, it didn't go away when I installed to a hard drive.

Furthermore, it didn't install cleanly. GRUB was set up incorrectly, and the xorg.conf was actually not quite right. I was willing to forgive all this - after all, GRUB hard disk nomenclature doesn't always coincide with Linux's, and the whole thing is based on Gentoo, so I could tweak the video drivers all I wanted. Or so I thought.

Unfortunately, 'emerge sync' managed to break Portage.

Three strikes, Kororaa. You were fun while you lasted. I might be back, someday, to manually install portage and try out some new video drivers, but don't count on it.

Sunday, May 13, 2007

Setting up my new Website with Joomla!

So I decided to build jonny-ash.com as a combination professional/personal resource. For employers, my site needs the following:

  • Contact information that is protected from spam-bots
  • Resume
  • Some "about me" information
  • References to this blog, which though unprofessional, does demonstrate my dedication to computer science.
For friends and family, I wanted:

  • Links to all my identities on different web resources (YouTube, MySpace, Flickr)
  • Aggregation (as much as possible) of those identities
This essentially really just boils down to a few use cases. I seriously considered doing it with PHP and calling it a day, but I decided to be adventurous and try getting out of the "coder" mindset and instead using an existing content management system - after all, this "Web 2.0" noise is essentially about using existing software over the web, rather than doing everything yourself. Since Joomla! has a canned installation system on DreamHost (my web host), it seemed like the clear choice.

Now that all is said and done, I'm actually fairly happy with Joomla! as a tool. It's a MySQL-backed system that does a good job of differentiating between style presentation, content, and navigation. You have a user-friendly backend which allows addition of content and drop-in style template changes (totally configurable, if you really care) and all the actual pages are generated with PHP. It's virtually seamless.

Of course, CSS allows us to separate style information from content in HTML, and this is generally good practice that is observed all over. But allowing navigation to remain distinct from content is something really handy, and it's great to be achieve it without using hack solutions (IMHO) like DreamWeaver.

It integrates neatly with Flickr and LiveJournal using Feed Gator as an extension. Blogger actually comes out pretty ugly because there's no "title" heading for Blogger entries, which makes everything pretty unreadable. There are tons of other components and modules that are freely available, as well, and some pretty slick templates.

So though it was overkill, and setup probably took twice what the PHP coding would have taken me, and although Joomla! is occasionally so complex that it gives me headaches, I'm pleased with my decision. Why? Well, mostly because now it takes .5 seconds to install a new theme and completely revamp my website's look. Having spent a summer to accomplish just that much for a college department in the old days, that's pretty danged satisfying.

Saturday, May 12, 2007

jonny-ash.com

Introducing jonny-ash.com.

I've finally invested in some real web hosting via DreamHost.

Wednesday, March 21, 2007

The ugly side of the "Web 2.0" approach

I recently did some work on my Google Summer of Code application. They want to know where my online resume is published. I put one up on Google docs and made it public. Now anyone can spider the Web and read my home address, phone number, and e-mail address. The e-mail addres was intentionally obfuscated from XYZ@gmail.com to "GMail: XYZ" in hopes that I won't be inundated with "VIxAy Gzzzz RA" and "hot nuked grils" in my inbox.

So now I find that I have the following:

So now we have tools like OpenID, but of the above, LiveJournal is the only one that supports it, so that helps, uh, none. Friend-of-a-friend is a machine-friendly method for describing relationships between people (like how we have "friends" on Facebook, and "friends" on LiveJournal, and "friends" flickr.) But again, nobody uses it, so that doesn't help.

So I could list on LJ, Facebook, Blogger, YouTube... etc, every one of this increasingly large list of content hosts. This is annoying, and it also means that a potential employer who reads my blog has to go to my Blogger profile to find my resume, and they'll also find things like my personal music work (which, honestly, isn't something that makes me feel at ease.) And really, I want my friends to know about my YouTube videos and music and such. And I shouldn't have to obfuscate my actual contact information in my resume or expect employers to use Facebook (heh).

So I'm now contemplating going whole-hog before my inbox gets spammed to death and just buying some web space and registering, say, jonny-ash.com. Here's what I want for myself:

Some web service which will keep track of my online identity in all its forms. Something that says "I am X on OpenID, Y on Blogger, Z on Flickr." I also want it to allow me to present myself in a professional way while keeping added goodies for people who want to know about me personally, and if possible, I'd like to restrict access to the personal stuff to friends. And lastly, I'd like it to have actual contact information that is protected from spiders and crawlers that sell my information to spammers.

The thing is, a service which *does* all this is totally possible. Nobody's done it yet.

I could.

Here's how it would work: It should support open standards like OpenID and FOAF. When a user logs in, they can set up an account with links to their various web resources. They should be able to add contact information and make it public or private but hide it behind a "verify that you are human" image so spiders can't read it. They should also be able to hide other information behind FoaF, as in, my "friends" and their "friends" (ideally, whether they are "friends" on Facebook, or LJ, or...) should be able to see my Aikido videos and music recordings. Other people shouldn't.

All of this should be pretty trivial to do, and I think I could get the web hosting for, say, $6 a month. I could sell advertising.

Would anyone be interested? Does anyone care? Should I just set up a personal website for myself and let everyone else do the same...?

Thursday, March 08, 2007

Finally, how to Really Parallelize *Any* Stackless DFA

I posted a little while ago about my idea for parallelizing a Huffman Decode. What I didn't realize at the time is that this could be generalized to parallelize any stackless DFA. Here's a simple writeup of a method for calculating the end state of a stackless DFA with input A, on a computer with infinite processors:

Break down the input, A, into N equal (or nearly equal) substrings, A1, A2... AN.

Next, create groups of processors, G0, G1, G2... GN. GN will be one processor, which will start in the start state of the automaton. Each Gi (where i > 0) will be run on groups of S processors, G1, G2... GN, where S is the number of states in the machine, and each processor in that group will start in a different state of the machine.

Each processor in Gi will process the input Ai.

Call G0 "finished" when it has either reached a "finish" state (e.g. SError, or, say, a "terminal" leaf in a tree). Call Gi where i > 0 "finished" when a processor in Gi-1 has been contacted by a prior group and that processor has finished processing all of its input.

When Gi finishes, it is either in a "finish" state (i.e. SError) or another state. If it is in a "finish" state, return this state. If it is in another state, it contacts the processor in Gi+1 which started in the state where Gi finished. The state returned by GN is the final state of the automaton.
Simple enough, right? Funny that I haven't seen this before - and that I hadn't thought of it sooner.


Realistic Applications

Of course, the real drawback here is that for speedup N, we need (N-1)*(S) processors (where S is the number of states in the machine). If we have very few states and a huge input, this could potentially be useful. However, if we have a huge number of states, we will require an even more huge number of processors to get a speedup. Furthermore, this is going to generate a lot of wasted cycles and drive up electricity bills, which is an increasing concern.

However, if we take this general method as a model for dealing with parallel DFA modeling, then it starts to get pretty useful. For example, in the Huffman Decoding method I described in a prior post, we know that the DFA is actually a tree, so group Gi only need to simulate the subtrees which start at a given depth (i.e. i * [len(A0) + len(A1) + ... + len(Ai-1)]), which is likely to be much smaller than the number of states in the DFA.

More generally, if we know beforehand what states are reachable after a given number of inputs (which can be computed easily), we can often reduce the number of processors which must be used.


Long-term, Pie-in-the-Sky Approaches

The approach I described before is actually very similar to some forms of branch prediction. A certain branch-predicting processor might look at a branch that happens on a conditional, then actually start computing two different trains of logic - one based on the assumption that the conditional will evaluate to "true," and one on the assumption that the conditional will evaluate to "false" (okay, so most processors are a little more complex, but that's the idea). When the conditional is evalutated, one of these strings of computation is thrown out and the results of the other are retained.

Imagine if our comnputer knew that a certain computation-heavy function would return one of X different values, and simply assigned a processor to make all of these assumptions, and the results from one of the X processors was retained. It's not all that different from the method I've described for simulating DFAs.

Granted, at this point, this approach is only useful if we know that the function will return one of a handful of known values. But what if we effectively had an infinite number of processors to throw at this problem? Say that we had a function which returns a 4-byte integer. That's quite a few possibilities, but what if we still just assigned a processor to each of them? If the number of cores in a processor doubles every 18 months, then we might actually be able to do something like this - and while it would be a dumb way to parallelize all our sequential code, it would still be possible to do entirely at the hardware level.

In the meantime, more formal languages allow us to specify the exact range of values a function could return. Again, this could make such a "shotgun" approach as I have described much less wasteful.

D-Wave's Quantum Computing Not Totally Legit

I've been trying to learn about that damned quantum computing demonstration from D-Wave for a while now. Ars Technica's article is the first one that's satisfied me.

The most important detail: Quantum computing, at least as D-WAVE has it, does not mean that NP-complete problems will be solvable in polynomial time. I had heretofore been under the impression that they might be.

Thus, computer scientists will not be rendered obsolete.

Thank you, Ars Technica, for clearing that up.

OpenBox is Great

I've grown disenfranchised with FluxBox. I'd been loyal, but I had some very strange issues with X/FluxBox going into a nasty freeze and the FB community was less-than-helpful.

I've tried Blackbox, and I have to say, it's too damned ugly. Admittedly, I never tried very hard at fixing that.

So today I tried OpenBox. It is a breath of fresh air. It is beautiful. It gets all my fonts right. And the more I learn about it, the better it seems. I think my first feeling of excitement came from reading the OpenBox "about" page:

Openbox works with your applications, and makes your desktop easier to manage. This is because the approach to its development was the opposite of what seems to be the general case for window managers. Openbox was written first to comply with standards and to work properly. Only when that was in place did the team turn to the visual interface.
Finally, a WM with it's head on straight.
The behavior is way more configurable than any WM I've seen before, because anything you can imagine is specifiable through an XML configuration file. While the difficulty of setting up a simple menu with XML is not easily overlooked, tools like denu greatly simplify the process.

One of the things that most impressed me was that they made a point of complying with freedesktop.org standards. If the post-fd.o world is really this well-done, the Free world will finally be a wonderful thing.